miércoles, enero 30, 2019

DRY with Kubernetes Operator Framework


Introduction:

An Operator is a method of packaging, deploying and managing a Kubernetes application. To make it, you use Kubernetes API to generate and deploy the application. You can think about a way of extending Kubernetes resources to be custom to your needs. This enables us to not have to repeat the same resource configuration every time but just the things that are different.

An example of an operator might be the deployment of service of your microservice architecture. For your service, you need to create a deployment file where you specify a lot of parameters such as the container, the deployment information, environment variables to configure the service, liveness and readiness probes, ... Then when you need to release a new version of this service, you just take this deployment file, you specify everything again but with one small change (the version part of docker image is updated). So everything is exactly the same except one field (the version part) and you apply the resource to Kubernetes cluster. Why you need to repeat everything every time you want to release a new version when the only important thing is the version number?

An Operator let you fix this. You specify all common part as a custom resource (write once) and then for every new version of the service you only need to create a new resource of kind custom resource, with only the uncommon part set, in our example the version number.

In a big simplification (I repeat a big simplification) you can think about Operators as a way to create a template with some dynamic values that are set in creation time. The biggest difference with a template is that the common content ("template") is created programmatically by the operator so you've got the freedom to change the resources dynamically.

Apart from that, with an Operator, you use Kubernetes API to decide when and how to deploy each of the resources.

Let's start with a really simple example which might help you understand how powerful is Operators and why you should start using them.

Suppose that I have one simple service which prints to console a message. This message is set in the command line section. So the resource file to deploy this service might look like:


As you can see it is fairly simple, but what's happen if now you want to deploy a new version of the service which instead of printing "Hello Alex", it prints "Hello Soto"? Well, you just need to create a new file which is exactly the same but changing the command line part. But instead of doing this, let's create an operator where you only need to specify the message to print, and the release of the service "just happens".

What you need:

To create an operator, for this guide you need:
Installing and booting up Minishift:

Minishift installation instructions can be found at (https://docs.okd.io/latest/minishift/getting-started/installing.html). After installation just run to prepare the cluster:

Creating the operator:

The first thing to do is prepare the layout for the Operator. Since we are going to create the Operator in Go, you need to create it in your GOPATH directory:


Then we need to add a new custom resource definition to this project, which will be responsible for defining how our custom resources look like:

We are generating a custom resource definition for a custom type called Hello.

Then we need to define the parameters that you want to set to the custom resource. These are the parts that you want to be different in every deployment. Let's say the version number or the message to print.

So let's define the spec and the status object.

Open pkg/apis/hello/v1alpha1/hello_types.go and add next fields:

You define in HelloSpec struct a field called Message that will contain the message you want to be printed when the container is started.

Then you need to run next command to update the generated code: operator-sdk generate k8s


Last part regarding code is to generate a controller which will be responsible for watching and reconciling our Hello resource. So run next command:


operator-sdk add controller --api-version=hello.lordofthejars.com/v1alpha1 --kind=Hello

The important file created after running this command is at pkg/controller/hello/hello_controller.go and in the next snippet you can see the important bits for our example:

Reconcile method reads the state of the cluster for our Hello object and makes any changes based on the sate and what is in the spec object.

The next important piece is the method newPodForCR which is a custom method that generates programmatically the resource that we want to use. You can think about it as the template, where you define the schema, and you use the Hello kind to fill the empty spaces. Notice that in this method there is the cr variable which is used to get the values from the custom resource. Let's modify this method to adapt to our requirements.

Installing the Operator:

Then you need to install the custom resource to the cluster, build the Operator Docker image and push it to Docker registry:

After that, you need to update the operator's definition to use the created image. Open deploy/operator.yaml and change REPLACE_IMAGE tag to lordofthejars/hello-operator:v0.0.1


And finally, we just need to create all Operator resources into the cluster:


If you run kubectl get pods now, you'll see the Operator deployed in the cluster (hello-operator-6d5559b65f-5zjg2   1/1       Running   0          25s).

Now that we have everything in place, it is time to see it in action. Create next file:

This is our resource where we are only specifying the message to be printed.

And finally, run oc/kubectl apply -f deploy/crds/hello_v1alpha1_hello_cr.yaml

Then you can check the log message by running oc/kubectl logs example-hello-pod


To remove the resource, you just need to do as usually oc/kubectl delete -f deploy/crds/hello_v1alpha1_hello_cr.yaml 


Now just update the hello_v1alpha1_hello_cr.yaml file to another message and apply the resource again. See the logs and boom the new message is printed.


So notice that now we are not doing a copy-paste anymore, we just create a file with the configurable parts, and that's all, everything else is managed by the operator.

Conclusions:

This is a really simple example, but you get the idea of how powerful is Operators and how they can simplify the way you deploy applications on Kubernetes.

We keep learning,
Alex

I don't know why you're not fair, I give you my love, but you don't care, So what is right and what is wrong?, Gimme a sign (What is Love - Haddaway)

Music: https://www.youtube.com/watch?v=HEXWRTEbj1I
Follow me at https://twitter.com/alexsotob


martes, enero 15, 2019

SerenityBDD for clean Rest API tests


Serenity BDD helps you write cleaner and more maintainable automated acceptance and regression tests faster. As his name suggests, it is a tool for BDD, but in this post, I am going to show you that can be used standalone (no Cucumber or JBehave specs) just JUnit for testing Rest APIs.

Serenity BDD also implements the screenplay pattern, which encourages good testing habits and improves the readability of the tests.

Although Serenity BDD was created first with built-in support for web testing with Selenium 2, currently it also supports Rest API testing by using Rest-Assured out-of-the-box.

So let's see how to write some tests using Serenity BDD for Rest API services. For this example, we are going to use ReqRes service which provides a simple Rest service with fake data, so you don't need to create a demo service anymore, just use one. We are going to create some integration test for this service which we can call it User Service.

At the end of the post, you'll be able to get the source code of the example, but for now, let's see the important bits.
In @Before section, we are just setting the URL of the service under test. In this case, the URL is set by using a system property called restapi.baseurl, but of course there are other ways to do that like using serenity.conf or serenity.properties files.
Then you also define the actor. This has the responsibility of doing the action, in this case, we named Security Service because in our example we suppose that the Security Service is the consumer and the User Service (implemented by ReqRes) is the provider.

Then we are defining two tests, and notice how is the actor who is responsible for doing the actions. attemptsTo (for doing the request), and should (for asserting the response). As you can see every test now it is really readable on what is the purpose. Check for example the find_an_individual_user() test method. You can read almost as natural language something like "security service attempts to find a user with id 1 and it should see that the response is (...)".

And if you are curious, the FindAUser class looks like;

You only take performAs method to implement the logic to do the request (in this case a Get method). Similar is done with other Http methods.

So you can see that it is not mandatory to use BDD approach for using Serenity BDD, you can use it for integration tests, without having to use any Http client nor REST-Assured directly with the big win of creating readable tests.

But there is one more thing to fell in love with Serenity BDD, and it is the reports it generates. If you start using it for BDD tests you'll see how powerful are its reports, being the live-documentation dream a reality, but if you are using just for integration tests, the generated reports are still impressive.


So you can have a quick overview of how your integration tests for a given service is behaving.

Serenity BDD is a really good choice for starting using BDD correctly, providing live-documentation to get the current state of the project and it integrates really well with Cucumber/JBehave as well as Selenium and REST-Assured. But if you are not into BDD or doing BDD-ish, then Serenity BDD is still a solution for just e2e tests (in case of monoliths) or integration tests.

Source code: https://github.com/lordofthejars/ReqRes-Serenity (mvn clean verify -Pdemo)

We keep learning,
Alex
Per tu, no sóc un dels teus amants, però creuo l'Himàlaia per tu, i robaré dotze diamants, un per cada lluna plena (Fins que arribi l'alba - Els Catarres)
Music: https://www.youtube.com/watch?v=Z5LVw2abUlw
Follow me at https://twitter.com/alexsotob


martes, enero 08, 2019

Auto-numbered Callouts in Asciidoctor


Asciidoctor 1.5.8 comes with a really nice feature which is called autonumber callouts, so you do not have to specify the number of the callout, but just a generic character (.) and then at rendering time, Asciidoctor will set the name correctly.

See the next example shows the number and auto-number feature for callouts:


And the output looks like:


So as you can see the output is exactly the same in both cases, but in the first case the number of the callout is static meanwhile in the second one autonumber feature is used.

Using autonumbering feature is really useful when you've got big blocks of code where you might introduce some callouts into already defined callouts which means a shifting of all of them.
Meanwhile, with the first approach means you need to go to every callout and increase the number manually, in the later one you only need to add a new callout and that's all, you do not need to go manually increasing the callout number.

We keep learning,
Alex.
My body is burning, it starts to shout, Desire is coming, it breaks out loud (Rock You Like Hurricane - Scorpions)

lunes, noviembre 19, 2018

Continuous Documentation with Antora and Travis

Antora is a documentation pipeline that enables docs, product, and engineering teams to create, manage, remix, and publish documentation sites composed in AsciiDoc and sourced from multiple versioned content repositories.

You can see several examples out there from Couchbase documentation to Fedora documentation. And of course, Antora documentation is used to generate Antora documentation. You can see it here.

So basically we have our project with documents in adoc format. Then what we want is regenerating the documentation every time a PR is merged to master.

In our project, we are using Travis-CI as CI server, so I am going to show you how we have done.

First of all, you need to create a .travis.yml file on the root of your project.


First, we define what we want to use. In this case docker and git.

Then in before_install section, we are detecting if we need to regenerate documentation or not.

Basically, we are going to generate documentation in two conditions:

  1. If commit message contains the word doc, then docs should be regenerated.
  2. If you have modified an adoc file from the documentation folder (or README.adoc) and the branch is master, then the docs should be regenerated.
If any of these conditions are met, then we configure git client with user, email and token to be used for pushing the generated documentation. Notice that this information comes from environment variable defined in Travis console. Also, it is important to note that the documentation should be generated in gh-pages branch (since we are releasing to GitHub pages). For this reason, we are using git worktree which checkouts the gh-pages branch in gh-pages directory.

Then in script section, we are just using Antora docker image to render documentation.

Finally, we just need to enter into gh-pages directory, create a .nojekyll file to avoid Git Hub Pages thinks that this is a Jekyll site, and finally push the changes.

And then for PR merged, the documentation is automatically regenerated and published.

Important: This script is based on one done previously by Bartosz Majsak (@majson) for Asciidoctor. My task has been only adapting it to use Antora.

We keep learning,
Alex.

Y no me importa nada nada (nada), Que rías o que sueñes, que digas o que hagas, Y no me importa nada, Por mucho que me empeñe, estoy jugando y no me importa nada (No me importa nada - Luz  Casal)


miércoles, octubre 03, 2018

Arquillian Chameleon Cheat Sheet


Arquillian Chameleon simplifies how we can write container tests in Arquillian, it has been out there for several times, but now in this post, I share with you a refcard so you can print and take a quick overview of its functionalities.


Special thanks to https://twitter.com/Mogztter for make it possible with its contribution to asciidoctor.js.

We keep learning,
Alex
You don't have to believe no more, Only got four hours, To learn your manners, Never felt so close to you before (King George - Dover)
Music: https://www.youtube.com/watch?v=wbM9RtOGdKE
Follow me at https://twitter.com/alexsotob

lunes, agosto 13, 2018

Java Iterator to Java 8 Stream


Sometimes during my work, I need to integrate with other libraries which they return an Iterator object instead of a list. This is fine from the point of view of libraries but it might be a problem when you want to use Java 8 streams on the returned iterator. There is one way to transform the Iterator to Iterable and then easily to stream.

Since all the time I need to remember how to do it, I decided to share the snippet here.


In the example, first of all, we have an Iterator class. Since Iterator cannot be used as a stream but an Iterable can do, we just create a new Iterable class which overrides its iterator() method to return the Iterator we want to stream.

Then we have an Iterable which is not streamable yet. So what we need to do is to use StreamSupport class to convert the Iterable to a Stream.

And that's all then you can use all streaming operations without any problem.

We keep learning,
Alex.
Prefereixo que em passis la birra que em tiris la canya, Perdona'm si em ric però es que em fas molta gràcia, Lligar no es lo teu, Em sap molt de greu (Lligar no és lo teu - Suu)
Music: https://www.youtube.com/watch?v=fWNqMjAVNto
Follow me at https://twitter.com/alexsotob

jueves, junio 07, 2018

Spring Boot + Cockroach DB in Kubernetes/OpenShift


In my previous post, I showed why CockroachDB might help you if you need a cloud native SQL database for your application. I explained how to install it in Kubernetes/OpenShift and how to validate that the data is replicated correctly.

In this post, I am going to show you how to use Cockroach DB in a Spring Boot application. Notice that Cockroach DB is compatible with PostgresSQL driver, so in terms of configuration is almost the same.

In this post, I assume that you have already a Cockroach DB cluster running in Kubernetes cluster as explained in my previous post.

For this example, I am using Fabric8 Maven Plugin to smoothly deploy a Spring Boot application to Kubernetes without having to worry so much about creating resources, creating Dockerfile and so on. Everything is automatically created and managed.

For this reason, pom.xml looks like:


Notice that apart from defining Fabric8 Maven Plugin I am also defining to use Spring Data JPA to make the integration between Spring Boot and JPA easier from the point of view of the developer.

Then you need to create a JPA entity and Spring Data Crud repository to interact with JPA.

Also, we need to create a controller who is responsible to get incoming requests, use the repository to make queries to DB and return results back to the caller.

Finally, you need to configure JPA to use the desired driver and dialect. In case of Spring Boot this is done in application.properties file.


The most important part here is that we need to use the PostgeSQL94 dialect. Notice that in url, we are using the postgresql jdbc url form. That's fine, since Cockroach uses the Postgres driver.

Now we need to create the database (customers) and the user (myuser) as configured in application.properties. To make it so, you just need to run cockroach shell and run some SQL commands:


Finally, you can deploy the application by running mvn clean fabric8:deploy. After that, the first time might take longer since needs to pull Docker images, you can start sending queries to the service.

As you can see it is really easy to start using a cloud-native DB like Cockroach DB in Spring Boot. If you want you can do exactly the same as in my previous post and start running queries to each of the nodes to validate that data is available correctly.

Code: https://github.com/lordofthejars/springboot-cockroach

We keep learning,
Alex.
Dôme épais, le jasmin, à la rose s'assemble, rive en fleurs, frais matin, nous appellent ensemble. (Flower Duet - Lakmé - Leo Delibes)
Music: https://www.youtube.com/watch?v=Vf42IP__ipw
Follow me at https://twitter.com/alexsotob


martes, mayo 29, 2018

CockroachDB. A cloud native SQL database in Kubernetes.


CockroachDB 2.0 has just been released. For those who don't know what it is, it can be summarized as a SQL database for the cloud era. One of the best things about CockroachDB is that it automatically scales, rebalances and repairs itself without sacrificing the SQL language. Moreover, Cockroach implements ACID transactions,  so your data is always in a known state.

In this post, I am going to explain how to install it in Kubernetes/OpenShift, insert some data and validate that it has been replicated in all nodes. In next post, I am going to show you how to use it with Spring Boot + JPA.

The first thing you need to have is a Kubernetes/OpenShift cluster to be used. You can use Minikube or Minishift for this purpose. In my case, I am using Minishift but I will provide equivalent commands for Minikube.

After having everything installed, you need to launch the Cockroach cluster.

In case of Kubernetes: kubectl create -f https://raw.githubusercontent.com/cockroachdb/cockroach/master/cloud/kubernetes/cockroachdb-statefulset.yaml

In case of OpenShift: oc apply -f https://raw.githubusercontent.com/cockroachdb/cockroach/master/cloud/kubernetes/cockroachdb-statefulset.yaml

Then you need to initialize the cluster:

In case of Kubernetes: kubectl create -f https://raw.githubusercontent.com/cockroachdb/cockroach/master/cloud/kubernetes/cluster-init.yaml

In case of OpenShift: oc apply -f https://raw.githubusercontent.com/cockroachdb/cockroach/master/cloud/kubernetes/cluster-init.yaml

Then let's configure the cluster so we can access the admin UI:

In case of Kubernetes: kubectl port-forward cockroachdb-0 8080

In case of OpenShift: oc expose svc  cockroachdb-public --port=8080 --name=r1

Now let's create a database and a table and see how it is replicated across all the cluster easily. Cockroach comes with a service that offers a load-balanced virtual IP for clients to access the database.

In case of Kubernetes: kubectl run cockroachdb -it --image=cockroachdb/cockroach --rm --restart=Never -- sql --insecure --host=cockroachdb-public

In case of OpenShift: oc run cockroachdb -it --image=cockroachdb/cockroach --rm --restart=Never     -- sql --insecure --host=cockroachdb-public

And finally in the opened console just type some SQL calls:

create database games;
use games;
create table game (id int, title varchar(30));
insert into game values (1, 'The Secret of Monkey Island');

So far, we have a new database, table, and entry in CockroachDB. Open admin UI, push Databases and you'll see something like this:


You can see that the database and the table have been created. Now let's see how we can know that everything has been replicated correctly. Push Overview and you'll see something like:


So pay attention to Replicas column. In all nodes, the number is exactly the same number, this means that all data in the cluster has been replicated X times.

Now let's increase by one the number of replicas and just refresh the page to see that the new node initially has not the same replica count.

In case of Kubernetes: kubectl scale statefulset cockroachdb --replicas=4

In case of OpenShift: oc scale statefulset cockroachdb --replicas=4


Another thing you can do is to just enter each container and validate that when connecting to localhost, the inserted data is there.

In case of Kubernetes: kubectl exec -it cockroachdb-0 /bin/bash

In case of OpenShift: oc exec -it cockroachdb-0 /bin/bash

Then inside the container just run: ./cockroach dump games --insecure

And you will see that CLI connects by default to the current node (localhost) and dumps the content of games db.

Repeat the same with other nodes cockroachdb-1 and cockroachdb-2 and you should see exactly the same.

So as you can see, it is really easy to use SQL in scale way thanks to Cockroach DB. In next post, we are going to see how to integrate Spring Boot + JPA with Cockroach DB, and deploying it into Kubernetes. 

We keep learning,
Alex
I can see a rainbow, In your tears as they fall on down, I can see your soul grow, Through the pain as they hit the ground (Rainbow - Sia)
Music: https://www.youtube.com/watch?v=paXOkGMyG8M

Follow me at https://twitter.com/alexsotob


lunes, marzo 26, 2018

Arquillian Chameleon. Simplifying your Arquillian tests.


Arquillian Chameleon was born to simplify the configuration of Arquillian tests. I am proud to announce that with version 1.0.0.CR2 we have not only simplified how to configure Arquillian tests but also how to write them.

With this new release, three new simplifications have been added:
  • You only need to use 1 (or at most 2 dependencies just in case you want to use auto-deployment feature)
  • It is not necessary to add any dependency to define which application server you want to use to run tests. Even not necessary to use arquillian.xml file to define it.
  • It is not necessary to use ShrinkWrap to build your package. You can still use it, but you can delegate the process of creating the package to a custom SPI.
So let's start.

Dependency

You only need to add one dependency you don't need to add Arquillian dependency + container dependency anymore.

Definition of container 

Now to define a container you just need to use a special runner and special annotation:

You just need to use ArquillianChameleon runner and the special annotation @ChameleonTarget to define which container you want to use. In this example, Wildfly 11 with the managed mode is configured.

When running this test, classpath is going to be configured with Arquillian Wildfly dependency, download the application server and behave as any other Arquillian test.


AutoDeployment

Arquillan allows you to define a Java SPI to describe how the archive should be created. This effectively means that no @Deployment method is required if you provide an implementation which automatically creates the deployment file.

Arquillian Chameleon provides at this time two implementations:
  1. File which deploys an already created file. You need to set the location of the file.
  2. Maven which runs using embedded Maven the build of the project and the generated archive is used as deployment archive.
For this example, I am going to use a multi-module project as an example, but notice that if you create a none multimodule project, then defaults works perfectly.


Notice that depending on the method you choose (File or Maven) you need to add the implementation on classpath.

In this case, I choose to use the Maven approach which means that the archive is generated by building all project.

Two things that are specific to this test and needs to be customized (instead of defaults) because of the example.

First one is the pom location. By default, the @MavenBuild annotation uses the pom.xml where the test is executed. In case of multimodule project, you don't want to run the build from module where test is defined but from the root of the project, so you get a complete archive with all dependencies. For this case you need to set it where is located.

The second one is where is the archive generated to be used to deploy. By default, you don't need to specify anything since in case of none multimodule project you are only generating one file. But in case of multimodule projects, you are generating multiple archives, so you need to specify which module contains the final archive.

And that's all, when you run this test, Arquillian will download Wildfly, start it, runs the build to get the final deployment file (such as .war), deploy it and finally run the test.

Notice that also there is @DeploymentParameters annotation which is not mandatory to be used, but allows you to configure the deployment as you do with @Deployment annotation, such as setting a deployment name or changing the mode from a container (the default one) to as client.


Conclusions

You can see that everything has been simplified a lot. The idea is to offer a similar experience that you get when running a Spring tests.

We keep learning,

Alex
Not knowing what it was, I will not give you up this time, But darling, just kiss me slow, your heart is all I own, And in your eyes you're holding mine (Perfect - Ed Sheraan)


lunes, febrero 12, 2018

Repeatable Annotations in Java 8


With Java 8 you are able to repeat the same annotation to a declaration or type. For example, to register that one class should only be accessible at runtime by specific roles, you could write something like:

Notice that now @Role is repeated several times. For compatibility reasons, repeating annotations are stored in a container annotation, so instead of writing just one annotation you need to write two, so in the previous case, you need to create @Role and @Roles annotations.

Notice that you need to create two annotations, one which is the "plural" part of the annotation where you set return type of value method to be an array of the annotation that can be used multiple times. The other annotation can be used multiple time in the scope where it is defined and must be annotated with @Repeatable annotation.

This is how I did all the time since Java 8 allows to do it. But last week, during a code review my mate George Gastaldi pointed me out how they are implementing these repeatable annotations in javax.validation spec.  Of course, it is not completely different but I think that looks pretty much clear from point of view implementation since everything is implemented within the same archive and also, in my opinion, the name looks much natural. 

Notice that now everything is placed in the same archive. Since usually you only need to refer to @Role class, and not @Roles (now @Role.List) annotation you can hide this annotation as an inner annotation. Also in case of defining several annotations, this approach makes everything look more compact, instead of having of populating the hierarchy with "duplicated" classes serving the same purpose, you only create one.

Of course, I am not saying that the approach of having two classes is wrong, at the end is about preferences since both are really similar. But after implementing repeatable annotations in this way, I think that it is cleaner and compact solution having everything defined in one class.

We keep learning,
Alex.
Jo sóc l'hipopòtam, i crec que el lleó, ha de refrescar-se per estar molt millor (El Lleó Vergonyós - El Pot Petit)
Music: https://www.youtube.com/watch?v=lYriMzzMsUw

Follow me at https://twitter.com/alexsotob


lunes, enero 08, 2018

Secret Rotation for JWT tokens


When you are using JSON Web Token (JWT), or any other token technology that requires to sign or encrypt payload information, it is important to set an expiration date to the token, so if the token expires, you can either assume that this might be considered a security breach and you refuse any communication using this token, or you decide to enable the token by updating it with new expiry date.

But it is also important to use some kind of secret rotation algorithm, so the secret used to sign or encrypt a token is periodically updated, so if the secret is compromised the tokens leaked by this key is less. Also in this way you are decreasing the probability of a secret being broken.

There are several strategies for implementing this, but in this post, I am going to explain how I implemented secret rotation in one project I developed some years ago to sign JWT tokens with HMAC algorithm.

I am going to show how to create a JWT token in Java.


Notice that what you need to do here is creating an algorithm object setting HMAC algorithm and set a secret that is used to sign and verify instance.

So what we need is to rotate this algorithm instance every X minutes, so the probability of breaking the secret, and that the broken secret is still valid, becomes very low.

So how to rotate secrets? Well, with a really simple algorithm that everyone (even if you are not a crypto expert) can understand. Just using time.

So to generate the secret, you need a string, in the previous example was secret String, of course, this is not so secure, so the idea is to compose this secret string by a root (something we called the big bang part) + a shifted part time. In summary the secret is <bigbang>+<timeInMilliseconds>

Bing bang part has no mystery, it is just a static part, for example, my_super_secret.

The interesting part is the time part. Suppose you want to renew secret every second. You only need to do this:

I am just putting 0s to milliseconds part, so if I run this I get something like:

1515091335543
1515091335500
1515091335500

Notice that although between second and third print, it has passed 50 milliseconds, the time part is exactly the same. And it will be the same during the same second.

Of course, this is an extreme example where the secret is changed every second but the idea is that you remove the part of the time that you want to ignore, and fill it with 0s. For this reason, first, you are dividing the time and then multiply by the same number.

For example, suppose that you want to rotate the secret every 10 minutes you just need to divide and multiply for 600000.

There are two problems with this approach that can be fixed although one of them is not really a big issue.

The first one is that since you are truncating the time if you want to change the secret every minute and for example, the first calculation occurs in the middle of a minute, then for just this initial case, the rotation will occur after 30 seconds and not 1 minute. Not a big problem and in our project, we did nothing to fix it.

The second one is what's happening with tokens that were signed just before the secret rotation, they are still valid and you need to be able to verify them too, not with the new secret but with previous one.

To fix this, what we did was to create a valid window, where the previous valid secret was also maintained. So when the system receives a token, it is verified with the current secret, if it passes then we can do any other checks and work with it, if not then the token is verified by the previous secret. If it passes, the token is recreated and signed with the new secret, and if not then obviously this token is invalid and must be refused.


To create the algorithm object for JWT you only need to do something like:


What I really like about this solution is:

  • It is clean, no need for extra elements on your system.
  • No need for triggered threads that are run asynchronously to update the secret.
  • It is really performant, you don't need to access an external system.
  • Testing the service is really easy.
  • The process of verifying is responsible for rotating the secret.
  • It is really easy to scale, in fact, you don't need to do anything, you can add more and more instances of the same service and all of them will rotate the secret at the same time, and all of them will use the same secret, so the rotating process is really stateless, you can scale up or down your instances and all instances will continue to be able to verify tokens signed by other instances.

But of course there are some drawbacks:

  • You still need to share a part of the secret (the big bang part) to each of the services in a secure way. Maybe using Kubernetes secrets, Vault from Hashicorp or if you are not using microservices, you can just copy a file into a concrete location and when the service is up and running, read the big bang part, and then just remove it.
  • If your physical servers are in different time zones, then using this approach might be more problematic. Also, you need that the servers are more or less synchronized. Since you are storing the previous token and current token, it is not necessary that they are synced in the same second and some seconds delay is still possible without any issue.


So we have seen a really simple way of rotating secrets so you can keep your tokens safer. Of course, there are other ways of doing the same. In this post, I just have explained how I did it in a monolith application we developed three years ago, and it worked really well.

We keep learning,
Alex.
You just want attention, you don't want my heart, Maybe you just hate the thought of me with someone new, Yeah, you just want attention, I knew from the start, You're just making sure I'm never gettin' over you (Attention - Charlie Puth)
Music: https://www.youtube.com/watch?v=nfs8NYg7yQM

Follow me at https://twitter.com/alexsotob

miércoles, enero 03, 2018

Cloud Native Applications with JWT


A native cloud application is an application that is developed for a cloud computing environment.

There is no specific answer to the question "what is a cloud-native application" but different concepts that must be met. 

One of the most important in my opinion is the ability to scale up and down at a rapid rate. And this means that our applications cannot have any state on each of the servers since if one server goes down or is scaled down, then the state stored in that server will be lost.

This is very well summarized at https://www.youtube.com/watch?v=osz-MT3AxqA where it is explained with a shopping cart example. In monolith approach, you store the products of the shopping cart in a server session, if the server went down then all products of shopping cart were lost as well. In a cloud-native app, where server instances can be scaled up and down quickly, it is important to not have this stateful behavior on your services and design them to be stateless.

There are different approaches to achieve this goal of implementing a stateless architecture but they can be summarized into two categories:
  • Use a distributed in-memory key/value data store like Infinispan.
  • Use a token which acts as a session between client and server using for example JWT.
In this post, I am going to introduce you the later approach.


JSON Web Token (JWT) is an open standard (RFC 7519) that defines a compact and self-contained way for securely transmitting information between parties as a JSON object.  

This information can be verified and trusted because it is digitally signed. JWTs can be signed using a secret using HMAC or a public/private key pair using RSA.

JSON Web Tokens consist of three Base64Url strings separated by dots which are: Header.Payload.Signature

So the idea basic idea for implementing stateless architecture on backend using JWT is the next one:
  1. When the user adds the first product, the backend service generates a new JWT token with the product added and sent it back to the frontend.
  2. When the user adds a new product, it sends the product to add and also the JWT token that was sent before by backend.
  3. Then the backend verifies that the token has not been modified (verifying the signature), then it gets the products from JWT payload added previously and add the new one to the list. Finally, it creates a new token with previous and new products and it sent it back to the frontend.
  4. The same process is repeated all the time.


So as you can see, now it is not necessary to maintain any state or add any new database service on backend side, you just need to sent back and forward the JWT token with the products inside.

I have recorded a video of a simple shopping cart example where I show the stateless nature of the solution. It can be seen at:


Also if you want to check the project that I used for recording you can take a look at https://github.com/lordofthejars/shop-jwt.

Notice that this is just a simple post so you can get the basic idea. But you need to take into consideration next things to use it in production:
  1. Use HTTPS instead of HTTP
  2. JWT just signs the token, if you want extra protection apart from HTTPS, use JWE to encrypt the payload of JWT token as well.
  3. Fingerprinting the token to avoid any man-in-the-middle attack and use these parameters as authentication parameters for the token.
  4. JWT can be used for passing authentication and authorization things as well.
You can watch my talk at JavaZone where I introduce some of these techniques:


The good part of JWT approach is that it simplifies a lot the deployment of the service, you don't need to deploy or configure any other distributed database to share the content across the cluster, which minimizes the problems related to the network for communicating to the distributed database or misconfiguring of any of the nodes.

The drawback is that the client needs to be aware to receive and sent back the token and deal with it. In backend side, you need to sign and verify every token all the time.

Note that this approach might work in some cases and might get into some troubles in others (for example if there are parallel connections to backend all of them modifying the token). This post just shows an example of how I implemented this stateless thing in a project with specific requirements, but in other cases it might be wrong to do it. A real shopping cart implementation would have some problems, but for the sake of simplicity and having a business model that everyone undertands, I decided to implement it in this way.

We keep learning,
Alex.
Turn it up, it's your favorite song (hey), Dance, dance, dance to the distortion, Turn it up (turn it up), keep it on repeat, Stumbling around like a wasted zombie (like a wasted zombie) (Chained to the Rhythm - Katy Perry)
Music: https://www.youtube.com/watch?v=Um7pMggPnug

Follow me at https://twitter.com/alexsotob
martes, enero 02, 2018

Writing end to end test for a microservices architecture


UPDATE: I was not really sure if I should call this post with e2e tests since I knew it can get some confusions, but I couldn0t think about any other name. After reading https://martinfowler.com/bliki/IntegrationTest.html I can be sure that what I am describing here is how to do Narrow Integration Test.

One of the main aspects of microservices architecture is that the application is formed as a collection of loosely coupled services each one deployable independently and communicated each other with some kind of light protocol.

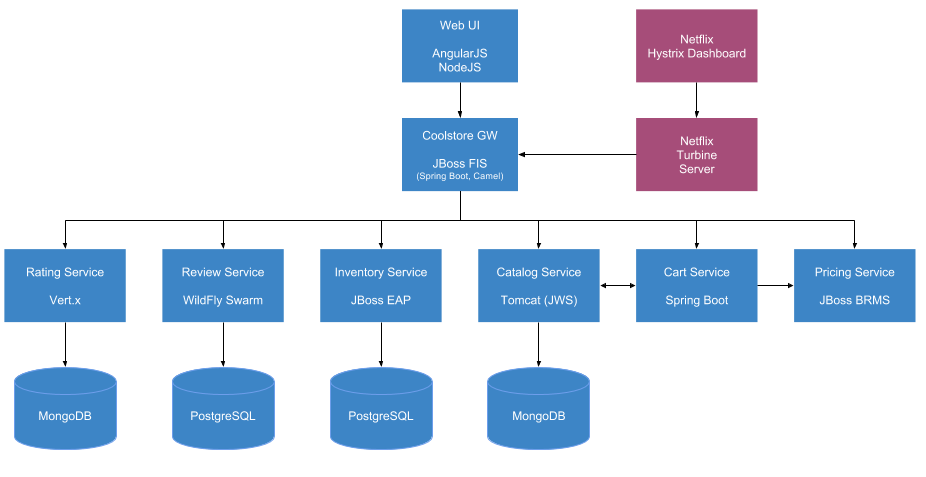
It is because of microservices architecture is a distributed system that makes writing end to end tests really hard. Suppose next simple example provided by Red Hat as an example of microservices architecture (https://github.com/jbossdemocentral/coolstore-microservice):


Now suppose that you want to write an end to end test for Cart Service. You will quickly see that it is not easy at all, let me enumerate some of the reasons:

  • Cart Service needs to know how to boot up Pricing Service, Catalog Service, and MongoDB (and if you want to involve the front-end as well then Coolstore GW and WebUI).
  • Cart Service needs to prepare some data (fixtures) for both of external services.
  • You communicate with services using a network. It might occur that some tests fail not because of a real failure but because of an infrastructure problem or because the other services have any bug. So the probability of these tests become flaky and start failing not because any changed introduced in current service is higher.
  • In more complex cases running these tests might be expensive, in terms of cost (deploying to the cloud), time (booting up all the infrastructure and services) and maintenance time.
  • Difficult to run them in developer machine, since you need all the pieces installed on the machine.

For this reason, the end to end tests is not the best approach for testing a microservice, but you still need a way to test from the beginning to the end of the service.

It is necessary to find a way to "simulate" these external dependencies without having to inject any mock object. What we need to do is cheat the service under test so it really thinks it is communicating with the real external services, when in reality it is not.

The method that allows us to do it is Service Virtualiztion.  Service virtualization is a method to emulate the behavior of component applications such as API based.

You can think about service virtualization as mocking approach you used to implement in OOP but instead of simulating at the object level, you simulate at the service level. It is mocking for the enterprise.

There are a lot of service virtualization tools out there, but in my experience, in the JVM ecosystem, one of the tools that work better is Hoverfly.

Let's see how an "end-to-end" test looks like for Cart Service.


This service is implemented using Spring Boot, so we are using Spring Boot Test framework. The important part here is that the URL where Catalog service is deployed is specified by using CATALOG_ENDPOINT property.  And for this test, it is set to catalog.

The next important point is the Hoverfly class rule section. In that rule next things are specified:
  1. An Http proxy is started before the test and all outgoing traffic from JVM is redirected to that proxy.
  2. It records that when a request to host catalog is done and the path is /api/products it must return a success result with given json document.

The test itself just uses TestRestTemplate (it is a rest client) and validates that you can add some elements to the cart.

Notice that you don't need to configure where the Http proxy is started or configure any port because Hoverfly automatically configures JVM network parameters so any network communication goes through Hoverfly proxy.

So notice that now you don't need to know how to boot up Catalog service nor how to configure it with correct data.

You are testing the whole service within its boundaries, from incoming messages to outgoing messages to other services, without mocking any internal element.

Probably you are wondering "What's happening in case of current  service has also a dependency on a database server?"

In this case, you do as usual since the service itself knows which database server is using and the kind of data it requires, you only need to boot up the database server, populate required data (fixtures) and execute tests. For this scenario I suggest you using Arquillian Cube Docker to bootup database service from a Docker container so you don't need to install it on each machine you need to run tests and Arquillian Persistence Extension for maintaining the database into a known state.

In next example of rating service, you can see briefly how to use them for persistence tests:


With this approach, you are ensuring that all inner components of the service work together as expected and avoiding the flakiness nature of end to end tests in microservices.

So end to end tests in any microservice is not exactly the same of an end to end test in a monolith application, you are still testing the whole service, but just keeping a controlled environment, where test only depends on components within the boundary of service.

How contract tests fit on this? Well actually everything showed here can be used in consumer and provider side of contract testing to avoid having to boot up any external service.  In this way, as many authors conclude, if you are using contract tests, these are becoming the new end to end tests.

viernes, diciembre 29, 2017

Java Champion


Before Christmas, I received the good news that I become a Java Champion. And then many memories came to my mind. My first computer, the ZX Spectrum that my parents bought me when I was 6, the first game I had, Desperado (http://www.worldofspectrum.org/infoseekid.cgi?id=0009331)  from TopoSoft. All programs that I copied from books in Basic language, all modifications I did and of course all the "pokers" that I copied from magazines to have infinite lives in games.

After that, it started the PC era, where I remember creating many "bat" files for having different memory configurations for playing games, editing saved files with Hex editors to have millions of resources and the appearance of Turbo C in my computer.

Finally, the internet era, that for me started in 1997, and my first browser which it was Netscape. What good old time, and then my first web page and JavaScript.

And this moves me towards the key point, I think it was at 1999 or 2000, I bought a magazine which it came with a CD-ROM with Java 1.2 there, I installed and I started programming in Java without IDE until today.

Probably this is the life of many of developers that were born in the 80s. 

But this is only "scientific" facts, not feelings. These days I have been thinking about the feelings I had, what ruled to me all this time, and it came to my mind the opening theme of one of my favorite TV program called "This is Opera". Exactly the same words can be applied in my case for programming/computing/Java.


I cannot finish without thanking all the people who I met over the globe during conferences, starting with Dan Allen (the first one I met at a conference), all Arquillian team, Tomitribe team with David Belvins at head), Asciidoctor community, Barcelona JUG guys and a lot of people, organizers, attendees, .... every one thank you so much for being there.

Of course, all the workmates I had in University (La Salle), in Aventia, Grifols (thanks to Erytra team, I enjoyed so much during all years I was there), Everis, Scytl, CloudBees (LLAP to Jenkins) and finally Red Hat, a company that I really love and I feel like home.

Last but not least my family who has been there all the time.

Next year I will continue posting more posts, contributing more to open source projects and of course going to speak to as many events as possible.

We keep learning,
Alex.
Caminante son tus huellas el camino y nada más: caminante, no hay camino se hace el camino al andar (Caminante No Hay Camino - Joan Manuel Serrat)


miércoles, octubre 25, 2017

Adding Chaos on OpenShift cluster


Pumba is a chaos testing tool for Docker and Kubernetes (hence OpenShift too). It allows you to add some chaos on containers instances such as stopping, killing or removing containers randomly. But it also adding some network chaos such as delaying, packet loss or re-ordering.

You can see in next screen recording how to add Pumba on OpenShift cluster and add some chaos on it.


The security calls that you need to run before deploying Pumba are the next ones:

Also the Kubernetes script to deploy Pumba in OpenShift is:


I have sent a PR to upstream Pumba project with this file but meanwhile is not accepted you can use it this one.

I'd like to say thank you to Slava Semushin and Jorge Morales for helping me on understanding the OpenShift security model.

We keep learning,
Alex.
Ce joli rajolinet, que les oques tonifique, si le fique en une pique, mantindra le pompis net (El baró de Bidet - La Trinca)
Music: https://www.youtube.com/watch?v=4JWIbKGe4gA

Follow me at https://twitter.com/alexsotob